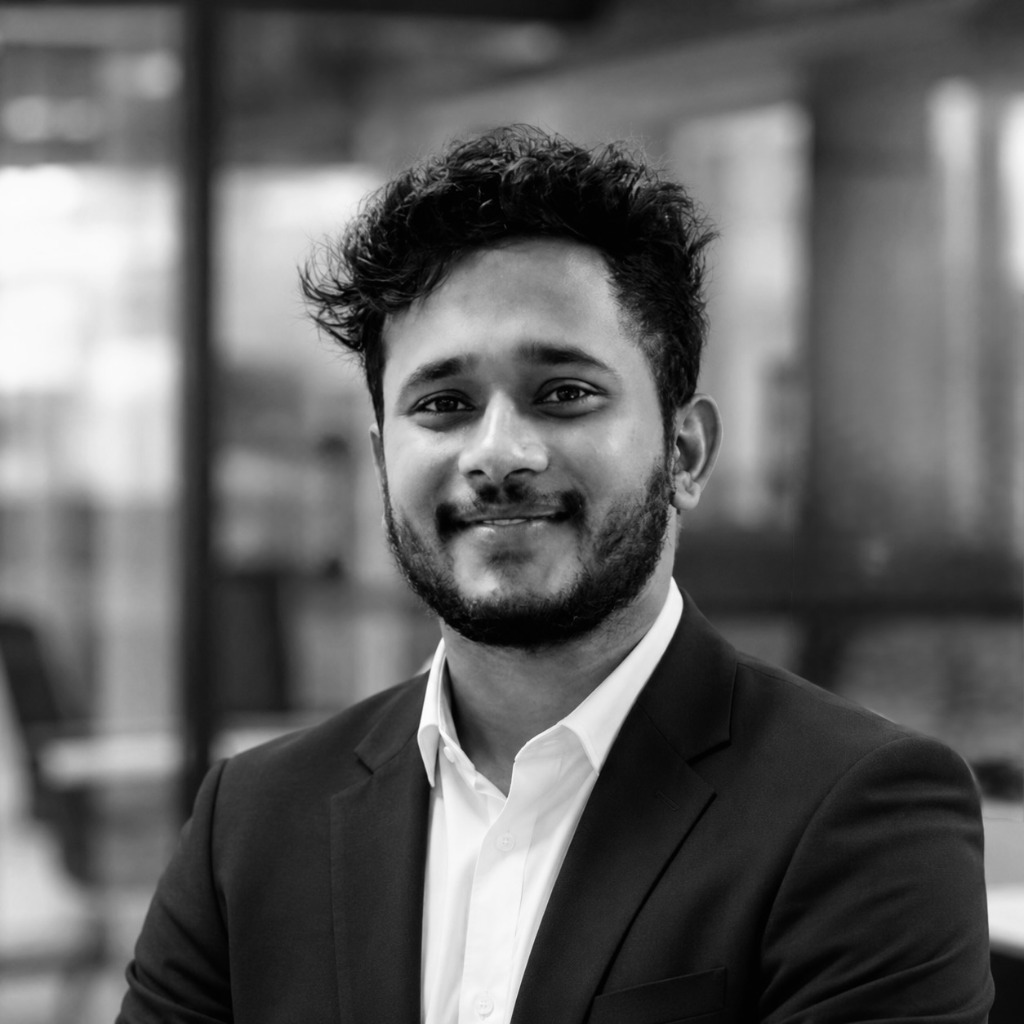
SENIOR DATA ENGINEER
5+ years delivering cloud-scale enterprise data platforms. Currently driving data platform transformation for Rabobank Netherlands, designing pipelines processing 1TB+ daily data with 99.9% reliability, achieving 40% Spark performance gains and 25% cost reduction.
Senior Data Engineer specializing in Azure Databricks, PySpark, and enterprise Lakehouses.
Senior Data Engineer with 5+ years of experience delivering cloud-scale data platforms on Microsoft Azure, specializing in Databricks, PySpark, and Lakehouse architectures. Currently working with Rabobank Netherlands, designing and optimizing data pipelines processing 1TB+ daily data with 99.9% reliability, achieving 40% performance improvements and 25% cost reduction.
Data Engineering & Cloud Ecosystem
Proven end-to-end tooling across Big Data pipelines, Medallion Lakehouses, infrastructure automation, and data governance.
Interactive Medallion Lakehouse Architecture
Click through each pipeline tier to inspect how 1TB+ daily financial data transitions from raw ingestion to enterprise reporting layers.
PySpark Deduplication & Validation
Cleansed, normalized, and schema-enforced Delta Lake tables. Complex join logic tuned using broadcast hashes and Z-ordering to strip duplicates and enforce banking GDPR rules.
Work Experience & Impact
Senior Data Engineer
AccentureClient: Rabobank, NetherlandsDesigned and optimized end-to-end data pipelines for Rabobank on Azure Databricks using PySpark and SQL, processing over 1TB of daily transactional data while maintaining 99.9% pipeline reliability within a Medallion Architecture.
Developed, scheduled, and monitored Databricks notebooks, jobs, and workflows for batch and incremental data processing.
Designed Lakehouse architectures and data models to support analytics, reporting, and downstream data consumption.
Improved data processing performance by 40% and reduced cloud infrastructure costs by 25% through advanced Spark tuning (broadcast joins, caching, partitioning) and query optimization.
Implemented enterprise-grade data governance for sensitive financial datasets using Unity Catalog, ensuring 100% compliance with GDPR and banking security standards across multiple production environments.
Supported Rabobank stakeholders during a 1-month onsite assignment in Utrecht, Netherlands, collaborating with local Dutch engineering teams to deliver data products 15% faster while maintaining 98% data accuracy.
Automated data platform deployments using Azure DevOps CI/CD (YAML pipelines), enabling version-controlled and repeatable releases across environments.
Data Engineer
LTI MindtreeClient: MicrosoftBuilt scalable end-to-end data pipelines using Azure Data Factory (ADF) and Azure Synapse Analytics to process large-scale datasets with high reliability.
Implemented cloud infrastructure automation and CI/CD using Terraform and Azure DevOps, ensuring consistent deployments across environments.
Worked directly with Microsoft internal teams as a client-facing Data Engineer, contributing to Azure-based data platforms and aligning solutions with Microsoft engineering standards and best practices.
Supported Azure data platform initiatives for a Microsoft enterprise client, following Microsoft-recommended architecture patterns, security standards, and performance guidelines.
Optimized SQL queries to improve performance and reduce system load, while providing technical guidance and mentorship to support team knowledge sharing.
Verified Professional Certifications
Certified technical authority across Databricks Big Data engineering and Microsoft Azure cloud infrastructure.
Databricks Certified Data Engineer Professional
Microsoft Certified: Azure Data Engineer Associate
Databricks Certified Data Engineer Associate
Microsoft Certified: Azure AI Fundamentals
Featured Data Engineering Systems

Enterprise Multi-Hop Lakehouse & Spark Optimizer
Designed and deployed end-to-end multi-hop Medallion data pipelines on Azure Databricks with PySpark and Delta Lake. Implemented broadcast joins, Z-ordering, query optimization, and caching, generating a 40% performance gain and 25% cloud infrastructure cost reduction.
Unity Catalog & Banking Security Compliance Engine
Engineered centralized access controls, fine-grained row/column-level data masking, and automated lineage tracking across multi-tenant financial environments at Rabobank. Collaborated on-site in Utrecht, Netherlands with local teams.
Scalable ETL/ELT Platform for Microsoft Ecosystem
Constructed resilient cloud data pipelines using Azure Data Factory and Synapse Analytics. Automated multi-environment infrastructure provisioning with Terraform and streamlined release pipelines with Azure DevOps YAML.

Automated Data Quality & Batch/Stream Orchestration
Configured Databricks Workflows, scheduled jobs, and Airflow DAGs for reliable batch ingestion and near-real-time streaming. Automated alerting, validation rules, and self-healing pipeline fallbacks.
Get In Touch with Praveen
Currently open to Senior Data Engineer and Databricks Lakehouse roles in product-based or global data-driven organizations.
{
  "protocol": "DISPATCH_TALENT_CONNECT",
  "recipient": "Praveen Kumar Katragunta",
  "credentials": "Databricks Certified Professional / Azure DP-203",
  "contact_details": {
    "email": "katraguntapraveenkumar02@gmail.com",
    "phone": "(+91) 8374927539",
    "linkedin": "linkedin.com/in/praveen-kumar-katragunta-32851918b",
    "website": "https://praveenkatragunta.com"
  },
  "sender": {
    "name": "TALENT_PARTNER_OR_DIRECTOR",
    "email": "hiring@enterprise.com"
  },
  "meta": {
    "role_intent": "Senior Data Engineer / Databricks Opportunity",
    "timestamp": "2026-09-21T00:00:00.000Z",
    "target_availability": "Actively interviewing for Senior Data / Lakehouse roles"
  },
  "message_payload": "Awaiting transmission input..."
}